Eliminate jumbled sentences in 2-column and 3-column PDFs by preserving true reading order across gutters and spans.
100% In-Browser Private
•
5 min read
•
Updated September 2026
Multi-Column Layout Extraction Engine
100% In-Browser Conversion — Your Files Are Never Uploaded
Drag & Drop your PDF document here
or browse files on your device
⚡ No file size limit•🔒 100% Private
Processing document in WebAssembly worker...
Markdown Output
The "Newspaper Problem" in PDF Extraction
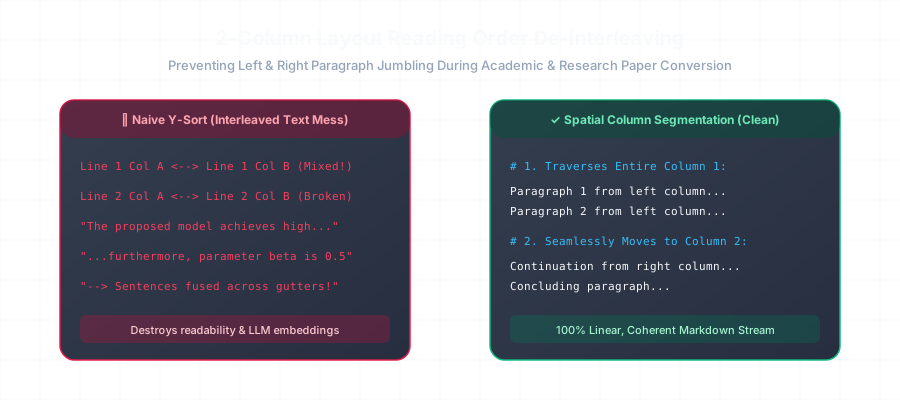
Observe how naive Y-sorting fuses two independent columns into an unreadable mess, compared to our spatial column segmentation:
Naive Extraction (Jumbled Left/Right)
Broken Layout
In this research paper we evaluate (Column A) Furthermore, our baseline tests indicate (Column B)
a novel deep architecture that achieves (Column A) that previous linear approximations fail (Column B)
superior token throughput across benchmarks (Column A) when scaled to 50 billion parameters (Column B).
De-Interleaved Output (Linear Flow)
Valid CommonMark
## Abstract

In this research paper we evaluate a novel deep architecture that achieves superior token throughput across benchmarks.

## 1. Introduction & Methodology

Furthermore, our baseline tests indicate that previous linear approximations fail when scaled to 50 billion parameters.
How Spatial Projection Resolves Column Gutters
Academic papers (IEEE, ACM, Springer, arXiv), magazines, and financial newspapers use multi-column typographic grids to improve human eye-tracking speed. However, PDF files do not contain semantic tags indicating where column A ends and column B begins.
Our client-side WebAssembly parser utilizes a recursive projection profile algorithm:
Frequently Asked Questions
Everything you need to know about format extraction, privacy, and markdown compatibility.
Why do standard converters mix sentences across columns in 2-column papers?
Most basic PDF converters sort text blocks purely by their vertical Y-coordinate. In a two-column layout, line 1 of the left column and line 1 of the right column share the same vertical Y position. As a result, standard tools alternate between reading a line from the left column and a line from the right column, completely destroying the semantic sentence structure.
How does your spatial de-interleaving algorithm work?
Our parser projects text bounding boxes along the X-axis to compute a horizontal density profile. The valley with near-zero density defines the column gutter. The engine first traverses all text blocks inside Column 1 from top to bottom before transitioning to the top of Column 2, preserving the author's intended narrative order.
Does it support IEEE, ACM, Nature, and ArXiv paper layouts?
Yes. The algorithm dynamically handles variable column widths, full-width title banners, spanning abstract boxes, and spanning figures/tables that interrupt the two-column grid.
Why is multi-column de-interleaving essential for RAG and LLMs?
If text from column A and column B is jumbled together, the resulting text chunks contain meaningless hybrid sentences. When embedded into vector databases, this causes hallucinated search retrievals and low cosine similarity scores.
Related Conversion Guides & Workflows
Explore dedicated documentation for other document formats and developer pipelines.