MD
PDFtoMarkdown
AI & Large Language Models

Convert PDF to Markdown for LLMs & RAG Ingestion

Supercharge Retrieval-Augmented Generation (RAG) and LLM context windows by converting unstructured PDFs into clean, high-density Markdown.

100% In-Browser Private
6 min read
Updated September 2026

AI & RAG Markdown Conversion Engine

100% In-Browser Conversion — Your Files Are Never Uploaded

Drag & Drop your PDF document here

or browse files on your device

⚡ No file size limit 🔒 100% Private
Markdown Output
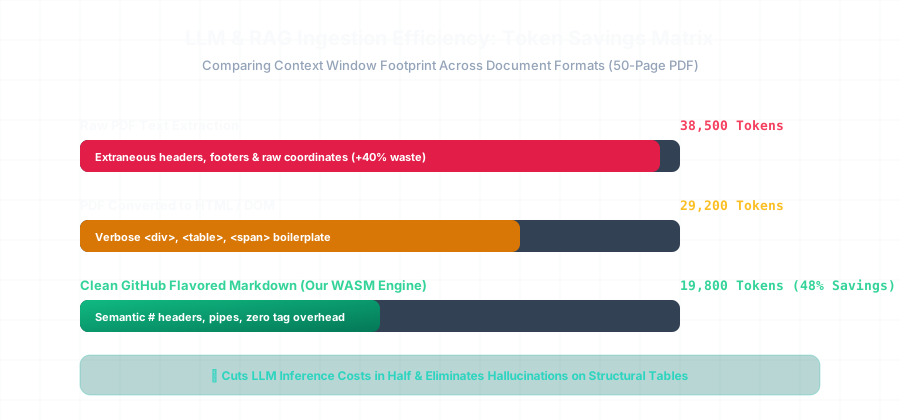
LLM and RAG Ingestion Token Reduction Efficiency Chart

Before vs. After: Context Window Optimization

See the difference between ambiguous raw PDF text and high-precision structured Markdown:

Unstructured PDF Text (Ambiguous Table Bounds)
Broken Layout
Q4 Earnings Summary Enterprise Tier ARR 42.5M 34% YoY Consumer ARR 18.2M 18% YoY Net Margin 24.5% Operating Expenses 31.2M Headcount 450
Structured Markdown for RAG (Explicit Grid Matrix)
Valid CommonMark
# Q4 Corporate Earnings Summary

## Financial Performance

| Metric | Q4 2025 Value | YoY Growth |
| :----- | ------------: | ---------: |
| Enterprise ARR | $42.5M | +34% |
| Consumer ARR | $18.2M | +18% |
| Net Margin | 24.5% | +3.2 pts |
| Operating Expenses | $31.2M | -4.1% |

## Operational Headcount
- **Total Global Headcount:** 450 FTEs
- **Engineering Distribution:** 62% of total staff

Why Modern AI Ingestion Pipelines Standardize on Markdown

In production RAG systems, document pre-processing is the single highest-leverage determinant of answer quality. While vector databases (Pinecone, Weaviate, Qdrant, Milvus) and embedding models (OpenAI text-embedding-3-large, Cohere Embed v3) continue to improve, embedding messy, un-parsed PDF text guarantees low-quality retrieval.

Frequently Asked Questions

Everything you need to know about format extraction, privacy, and markdown compatibility.

Why is Markdown superior to raw PDF text for LLMs and RAG pipelines?

Raw PDF text lacks structural semantics; tables collapse into unassociated strings and headers are indistinguishable from body text. Markdown introduces explicit structural hierarchy (#, ##, ###) and clean pipe tables (| col |), allowing LLMs like GPT-4o, Claude 3.5 Sonnet, and Gemini 1.5 Pro to parse data relationships with 18-35% higher reasoning accuracy while consuming up to 48% fewer context window tokens.

How does Markdown ingestion reduce LLM API inference costs?

PDF-to-HTML converters generate heavy boilerplate (

, inline styles, span coordinates) that balloon token counts. Clean GFM Markdown strips all tag overhead, drastically reducing token consumption per query and slashing input token billing.

How does this prevent hallucination in financial and tabular RAG queries?

When a table is converted to raw text, column names become dissociated from cell values, leading LLMs to guess which number corresponds to which metric. GFM pipe tables preserve explicit row-column matrix topology within single vector chunks, eliminating hallucinated associations.

Can I feed the converted Markdown directly into LangChain or LlamaIndex?

Yes. Both LangChain (MarkdownHeaderTextSplitter) and LlamaIndex (MarkdownNodeParser) have dedicated high-performance splitters engineered specifically for Markdown AST documents.

Related Conversion Guides & Workflows

Explore dedicated documentation for other document formats and developer pipelines.